Build the future of
homegrown AI.
We research and build models every team can use, train, and trust.
Read our researchFrontier-level results, on your terms
99%
lower cost than Claude Opus 5
and 96% lower than GPT-5.6 Luna
+18%
better after training
ROUGE-1, same model before and after
23×
faster than Claude Opus 5
and 6× faster than GPT-5.6 Luna
Measured in our study on a summarization benchmark (QMSum). Read the paper
A fraction of the running cost.
Once usage passes the crossover, owning the model costs less than paying per token.
- Frontier API
- Custom model on cloud
- Custom model on-device
- Your savings
Illustrative. The crossover depends on your task and hosting.
Full control.
Runs where you deploy it.
On-device, your cloud or on-premise.
Pinned to the version you tested.
Changes only when you retrain.
Behavior set by your examples.
Tone, format and refusals come from your data.
Your data stays private.
The model is yours to download.
The research behind our models.
All researchRight-sized specialists
How small a model trained for one task can be while matching a frontier model on it.
Paper · Aug 2026
Read the paper
Models that learn from traffic
How production requests and feedback become training data, and how a new version earns its place.
In design-partner pilots
Agentic unit economics
Where AI spend goes, and what it costs to run agents at scale.
Analysis · 12 Oct 2026
Read the analysis
Models trained for the job
Agent pipelines run the same defined tasks thousands of times a day. Give each step a small model trained for that task, and it delivers frontier-level results at a fraction of the running cost.
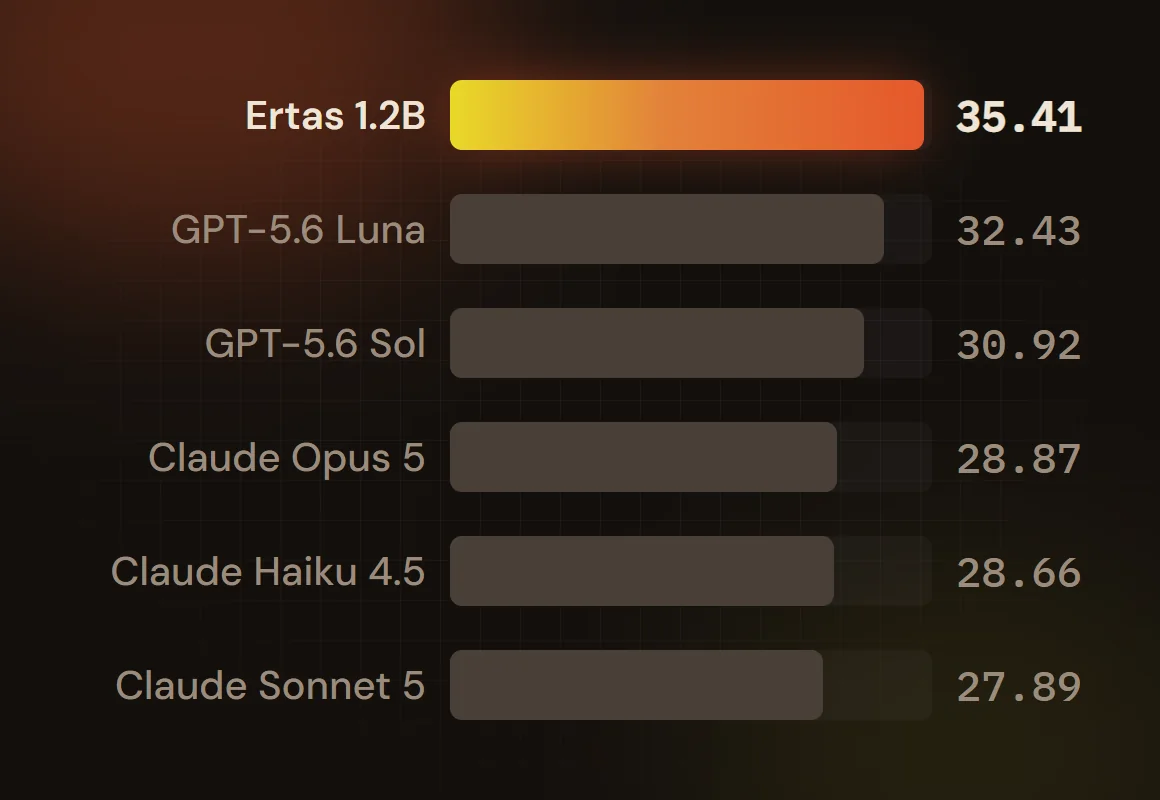
Read the paper35.41 vs 32.43
On a summarization benchmark (QMSum), our trained 1.2B summarizer against the best of five hosted proprietary models, Claude Opus 5 and GPT-5.6 among them, on ROUGE-1. A 406M model we trained scored 36.33. Both are over 1,000 times smaller than a frontier model and run on your own hardware, with no per-token fees.
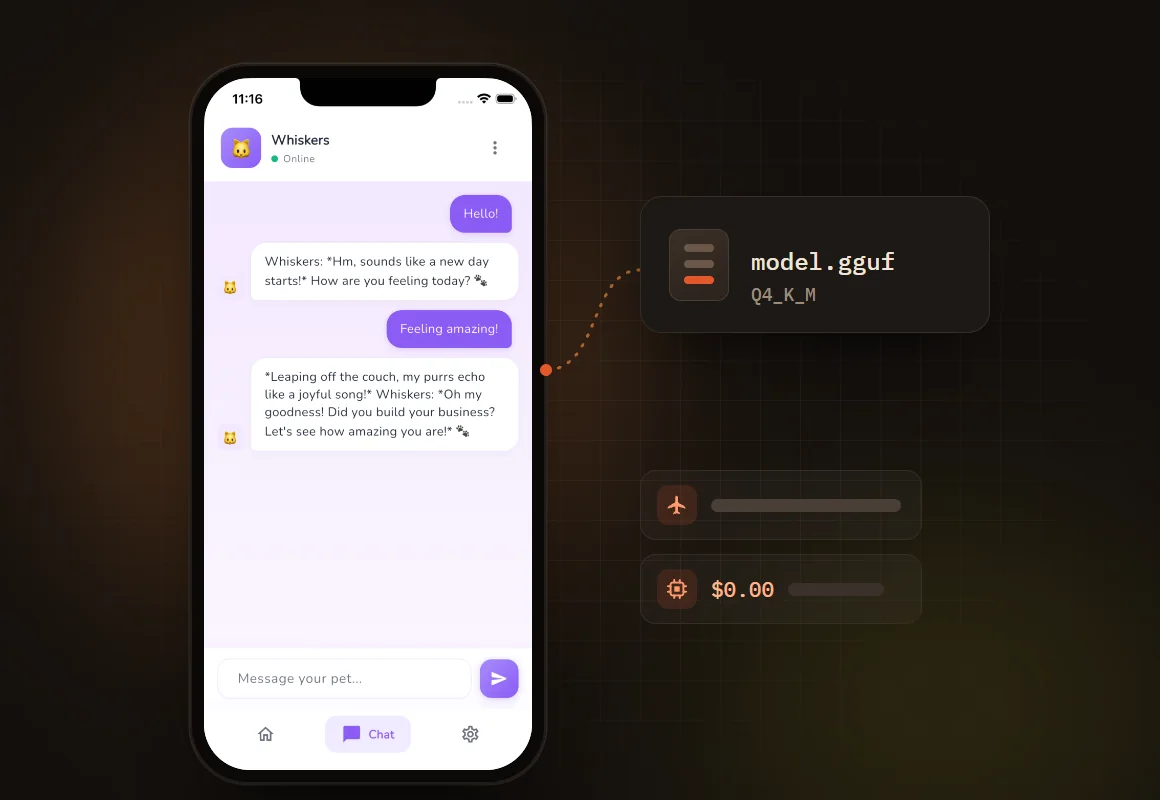
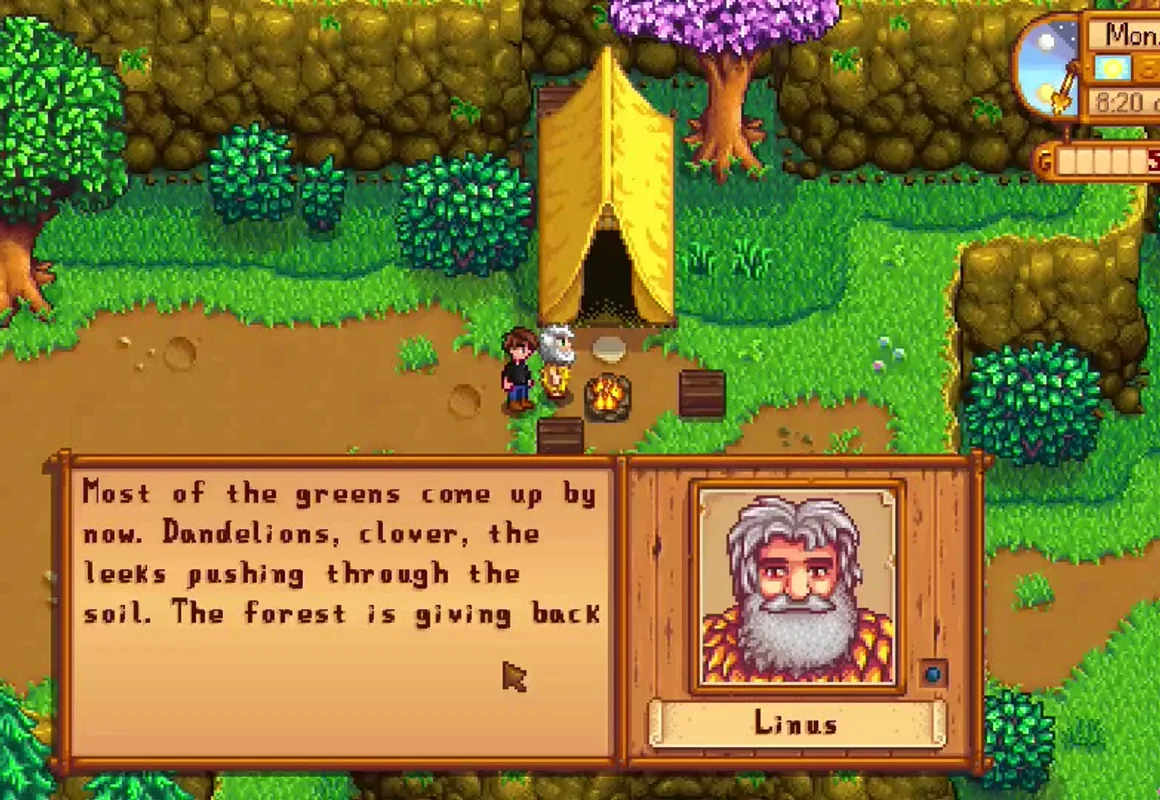
Chatty Valley gives a Stardew Valley villager open conversation that stays in character. One small base model runs on the player's own machine, and each character is a lightweight adapter on top of it.
Read the build story21 MB
holds Linus's whole personality, as an adapter on a shared 1.2B base model that runs locally.
Ship a model trained for your feature inside your iOS, Android or desktop app, working offline with user data kept on the device. Using an off-the-shelf API model today? The adaptive model endpoint can serve your trained model for you.
Adaptive endpointSee the on-device cost math$0
per inference, with the model running on the user's device.
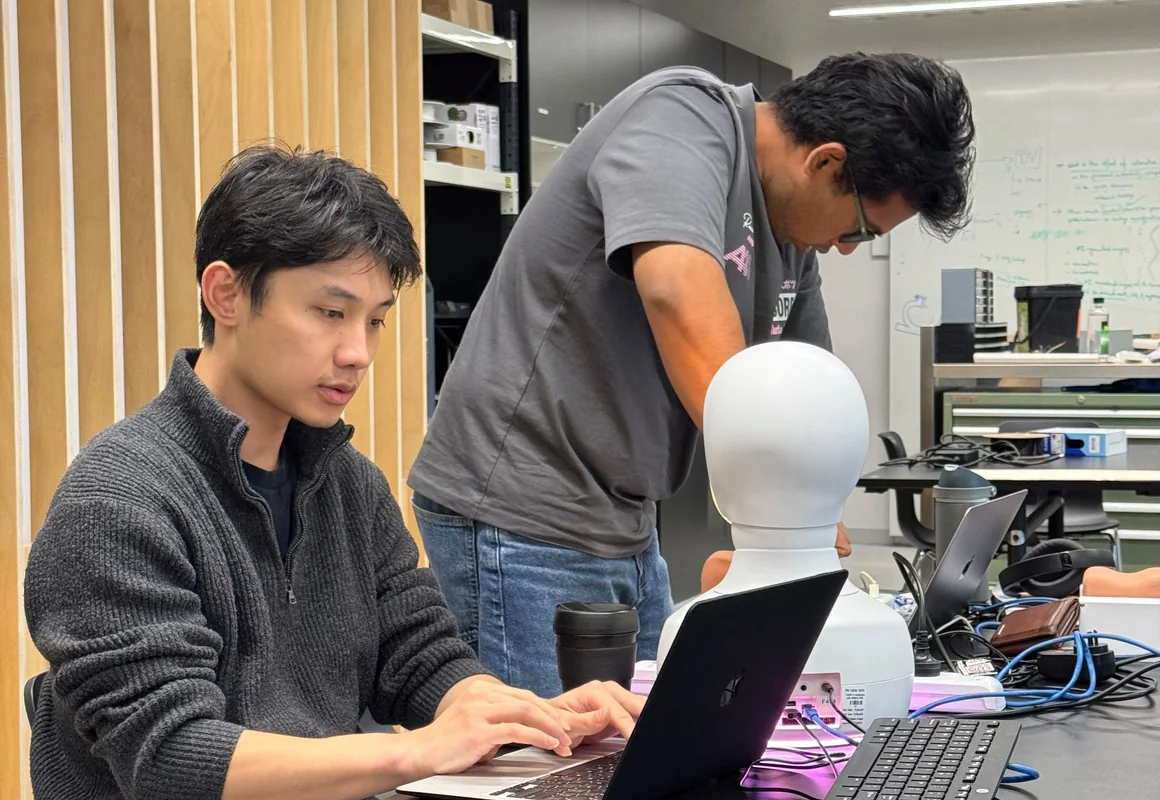
An AI patient for physiotherapy education. Students examine a physical simulator and ask questions out loud, and a small model trained on Ertas answers as the patient, consistent from one question to the next, on the simulator's own hardware.
Sept 2026
shown live at Melbourne Connect Innovation Week. Full case study coming soon.
01 / 04
Specialist agents
Agent pipelines run the same defined tasks thousands of times a day. Give each step a small model trained for that task, and it delivers frontier-level results at a fraction of the running cost.
35.41 vs 32.43
On a summarization benchmark (QMSum), our trained 1.2B summarizer against the best of five hosted proprietary models, Claude Opus 5 and GPT-5.6 among them, on ROUGE-1. A 406M model we trained scored 36.33. Both are over 1,000 times smaller than a frontier model and run on your own hardware, with no per-token fees.
Read the paperSpecialist agents
Agent pipelines run the same defined tasks thousands of times a day. Give each step a small model trained for that task, and it delivers frontier-level results at a fraction of the running cost.
Read the paper35.41 vs 32.43
On a summarization benchmark (QMSum), our trained 1.2B summarizer against the best of five hosted proprietary models, Claude Opus 5 and GPT-5.6 among them, on ROUGE-1. A 406M model we trained scored 36.33. Both are over 1,000 times smaller than a frontier model and run on your own hardware, with no per-token fees.
Game development
Chatty Valley gives a Stardew Valley villager open conversation that stays in character. One small base model runs on the player's own machine, and each character is a lightweight adapter on top of it.
Read the build story21 MB
holds Linus's whole personality, as an adapter on a shared 1.2B base model that runs locally.
App development
Ship a model trained for your feature inside your iOS, Android or desktop app, working offline with user data kept on the device. Using an off-the-shelf API model today? The adaptive model endpoint can serve your trained model for you.
Adaptive endpointSee the on-device cost math$0
per inference, with the model running on the user's device.
Professional training
An AI patient for physiotherapy education. Students examine a physical simulator and ask questions out loud, and a small model trained on Ertas answers as the patient, consistent from one question to the next, on the simulator's own hardware.
Sept 2026
shown live at Melbourne Connect Innovation Week. Full case study coming soon.
Work with us.
One endpoint that gets cheaper and better with use.
We train, deploy and keep improving a custom model on your traffic. Each new version takes over only after it passes your evals.
Self-serve
Train and deploy custom models yourself.
Build a dataset, train open models on cloud GPUs through a visual canvas, and export them to run anywhere, including on-device.
Building in Brunswick, Melbourne.
Meet the team